
Qwen (Alibaba)
Qwen3-Coder-30B-A3B-Instruct
A 31B mixture-of-experts (about 3B active) coding model by Qwen (Alibaba) that uses tools such as web search and can think before answering.
Coding Tools Thinking- Downloads
- 745,022 downloads last month
- Likes
- 1,163 likes
- Uploaded
- Uploaded 31 Jul 2025
- Parameters
- 30,532,122,624 (30.5B)
- Context length
- 262,144 tokens
- Architecture
- qwen3moe
- Task
- text-generation
- Licence
- apache-2.0
- Released
- 31 Jul 2025
- Last updated
- 3 Dec 2025
This is unsloth's upload of Qwen/Qwen3-Coder-30B-A3B-Instruct.
Read the licence: apache-2.0
Tools
Uses tools, so web search and the browser work best with it.
Thinking
Can think step by step before it answers.
Each version is the same model stored at a different precision: smaller files use less memory and lose a little quality.
| Version | File size | File | SHA-256 |
|---|---|---|---|
| UD-TQ1_0 | 8.01 GB | Qwen3-Coder-30B-A3B-Instruct-UD-TQ1_0.gguf | |
| UD-IQ1_S | 8.91 GB | Qwen3-Coder-30B-A3B-Instruct-UD-IQ1_S.gguf | |
| UD-IQ1_M | 9.63 GB | Qwen3-Coder-30B-A3B-Instruct-UD-IQ1_M.gguf | |
| UD-IQ2_XXS | 10.33 GB | Qwen3-Coder-30B-A3B-Instruct-UD-IQ2_XXS.gguf | |
| UD-IQ2_M | 10.84 GB | Qwen3-Coder-30B-A3B-Instruct-UD-IQ2_M.gguf | |
| Q2_K | 11.26 GB | Qwen3-Coder-30B-A3B-Instruct-Q2_K.gguf | |
| Q2_K_L | 11.33 GB | Qwen3-Coder-30B-A3B-Instruct-Q2_K_L.gguf | |
| UD-Q2_K_XL | 11.79 GB | Qwen3-Coder-30B-A3B-Instruct-UD-Q2_K_XL.gguf |
Show all 27 versionsHide the other versions
- Model class
- Qwen3MoeForCausalLM
- Model type
- qwen3_moe
- Layers
- 48
- Hidden size
- 2048
- Attention heads
- 32
- Key/value heads
- 4
- Experts
- 128 (8 used per token)
- Vocabulary
- 151,936
- Context length
- 262,144 tokens
- Weights
- bfloat16
Recommended settings
From generation_config.json in Qwen/Qwen3-Coder-30B-A3B-InstructThe sampling settings the model's makers ship as its defaults.
- Temperature
- 0.7
- Top P
- 0.8
- Top K
- 20
- Repetition penalty
- 1.05
Papers and data
From Qwen/Qwen3-Coder-30B-A3B-InstructPapers the model's Hugging Face page links to (the model's own report and papers it cites).
Qwen3-Coder-30B-A3B-Instruct
Highlights
Qwen3-Coder is available in multiple sizes. Today, we're excited to introduce Qwen3-Coder-30B-A3B-Instruct. This streamlined model maintains impressive performance and efficiency, featuring the following key enhancements:
- Significant Performance among open models on Agentic Coding, Agentic Browser-Use, and other foundational coding tasks.
- Long-context Capabilities with native support for 256K tokens, extendable up to 1M tokens using Yarn, optimized for repository-scale understanding.
- Agentic Coding supporting for most platform such as Qwen Code, CLINE, featuring a specially designed function call format.
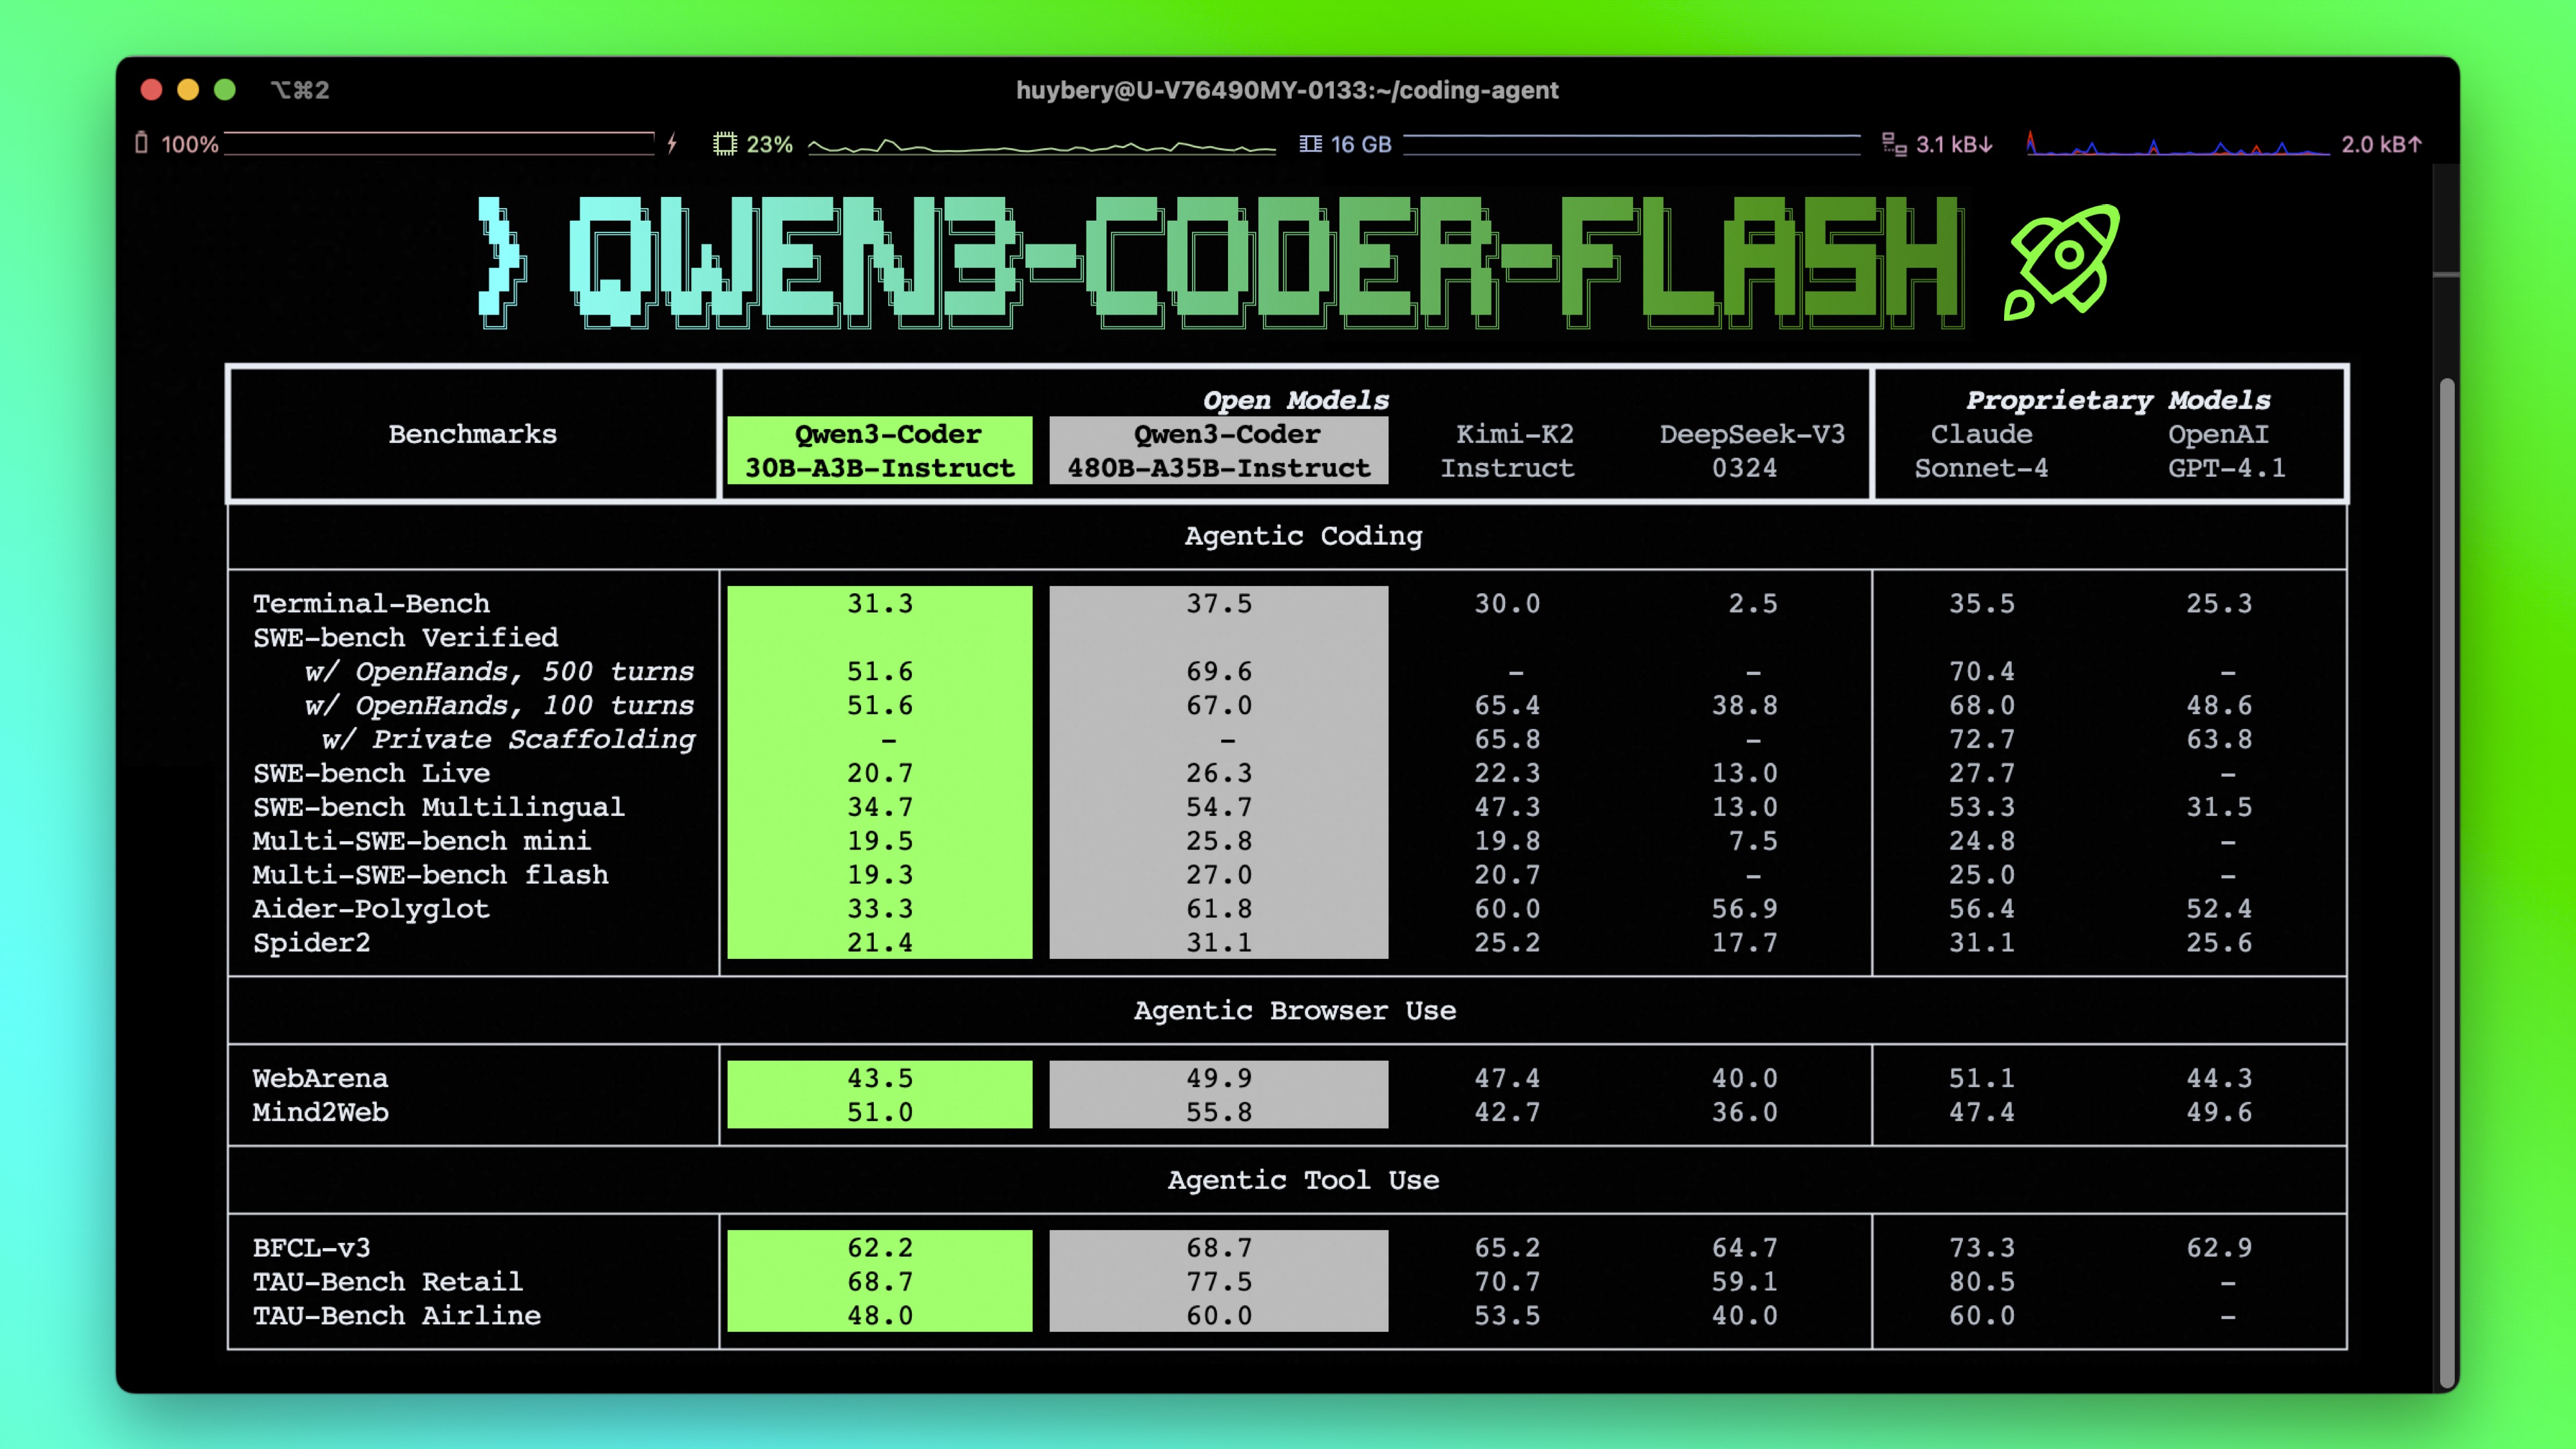
Model Overview
Qwen3-Coder-30B-A3B-Instruct has the following features:
- Type: Causal Language Models
- Training Stage: Pretraining & Post-training
- Number of Parameters: 30.5B in total and 3.3B activated
- Number of Layers: 48
- Number of Attention Heads (GQA): 32 for Q and 4 for KV
- Number of Experts: 128
- Number of Activated Experts: 8
- Context Length: 262,144 natively.
NOTE: This model supports only non-thinking mode and does not generate <think></think> blocks in its output. Meanwhile, specifying enable_thinking=False is no longer required.
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our blog, GitHub, and Documentation.
Quickstart
We advise you to use the latest version of transformers.
With transformers<4.51.0, you will encounter the following error:
KeyError: 'qwen3_moe'
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "Qwen/Qwen3-Coder-30B-A3B-Instruct"

# load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
    model_name,
    torch_dtype="auto",
    device_map="auto"
)

# prepare the model input
prompt = "Write a quick sort algorithm."
messages = [
    {"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True,
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)

# conduct text completion
generated_ids = model.generate(
    **model_inputs,
    max_new_tokens=65536
)
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()

content = tokenizer.decode(output_ids, skip_special_tokens=True)

print("content:", content)
Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as 32,768.
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
Agentic Coding
Qwen3-Coder excels in tool calling capabilities.
You can simply define or use any tools as following example.
# Your tool implementation
def square_the_number(num: float) -> dict:
    return num ** 2

# Define Tools
tools=[
    {
        "type":"function",
        "function":{
            "name": "square_the_number",
            "description": "output the square of the number.",
            "parameters": {
                "type": "object",
                "required": ["input_num"],
                "properties": {
                    'input_num': {
                        'type': 'number',
                        'description': 'input_num is a number that will be squared'
                        }
                },
            }
        }
    }
]

import OpenAI
# Define LLM
client = OpenAI(
    # Use a custom endpoint compatible with OpenAI API
    base_url='http://localhost:8000/v1',  # api_base
    api_key="EMPTY"
)

messages = [{'role': 'user', 'content': 'square the number 1024'}]

completion = client.chat.completions.create(
    messages=messages,
    model="Qwen3-Coder-30B-A3B-Instruct",
    max_tokens=65536,
    tools=tools,
)

print(completion.choice[0])
Best Practices
To achieve optimal performance, we recommend the following settings:
-
Sampling Parameters:
- We suggest using
temperature=0.7,top_p=0.8,top_k=20,repetition_penalty=1.05.
- We suggest using
-
Adequate Output Length: We recommend using an output length of 65,536 tokens for most queries, which is adequate for instruct models.
Citation
If you find our work helpful, feel free to give us a cite.
@misc{qwen3technicalreport,
      title={Qwen3 Technical Report},
      author={Qwen Team},
      year={2025},
      eprint={2505.09388},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2505.09388},
}
More from Qwen (Alibaba)
On Hugging Face
Everything on this page comes from these pages and is refreshed every few hours; Hugging Face always has the latest.